When MCP earns its overhead, and when a direct API is better
One question settles most of these arguments: will more than one AI application need this capability?
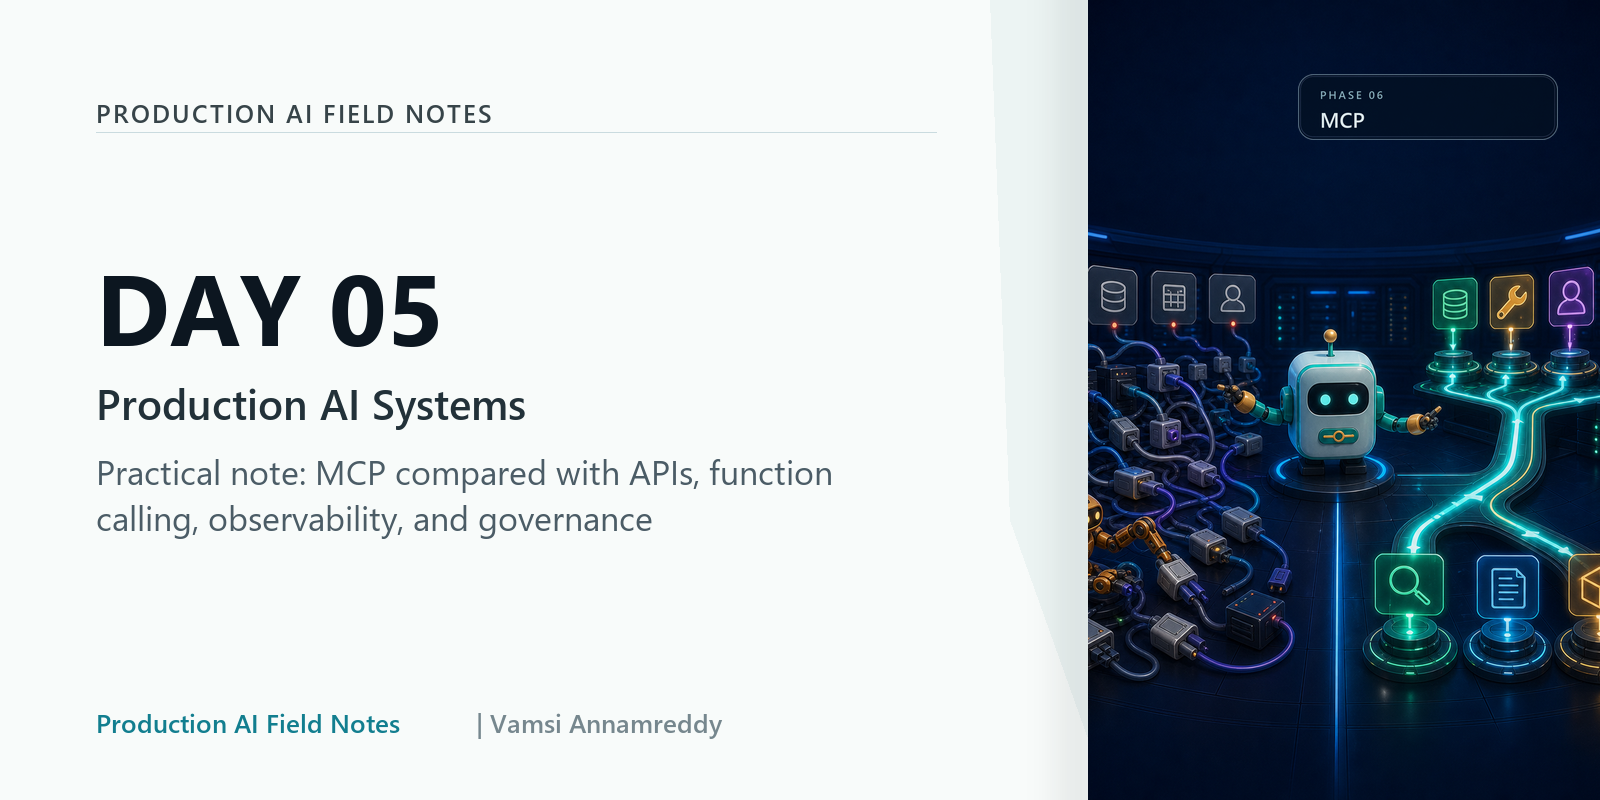
Teams tend to land in one of two ditches. Either MCP goes everywhere, including in front of an internal function the app already calls directly, or it goes nowhere and every AI feature reimplements the same integration with slightly different bugs.
Both come from skipping the question rather than answering it badly.
The question that settles it
Will more than one AI application need this capability?
If the answer is no, and it is honestly no rather than aspirationally no, a direct API call is better. You keep the call stack short, the failure modes obvious and the debugging local. Wrapping an internal function in a protocol layer to reach your own database is ceremony.
If the answer is yes, MCP starts paying for itself, because the things it standardises are exactly the things that get reinvented inconsistently: discovery, schemas, error shapes, session handling.
| Situation | Reach for |
|---|---|
| One app, internal function, stable contract | Direct API call |
| One app, model needs to choose when to act | Function calling |
| Several AI clients, same capability | MCP server |
| Capability owned by a different team | MCP server |
| Third parties will connect to it | MCP server, with real versioning |
Where the overhead is real
MCP costs you a process boundary, a schema contract and something new to operate. That last one is the part teams underestimate.
An MCP server other people depend on is a platform component. It needs release notes, because a schema change is a breaking change. It needs traces correlated with the calling agent, or debugging becomes archaeology across two systems. It needs tests that run when the underlying API changes, not when someone remembers.
If nobody is prepared to own those, the honest choice is a direct call today and an MCP server when a second consumer actually appears. Speculative platform work ages badly.
Where it clearly wins
Reusable, AI-facing capability surfaces that several clients need to discover at runtime. Anything crossing a team boundary, where a described contract beats a shared Slack thread. Anything you want a consistent audit trail for, regardless of which application triggered it.
That is a narrower set than the enthusiasm suggests, and a much better hit rate.
Choose the boundary on purpose. The cost of the wrong choice is not that it fails immediately, it is that it works just well enough that nobody revisits it.
Part 5 of 5 Days of MCP for Production AI.